

Data Schema In DBMS Powerpoint Presentation Slides




Try Before you Buy Download Free Sample Product
 Impress Your
Audience
 100%
Editable
 Save Hours
of Time


Our comprehensive Data Model in DBMS deck encompasses the essential elements required for effective data analytics. The data model template serves as the core foundational work, providing a structured framework for storing data in databases. Moreover, our professionally crafted DBMS PPT offers a concise overview of the data model, highlighting its conceptual tools and aiding in explaining the database architecture. In addition, the Data Schema presentation also includes tables, foreign keys, primary keys, views, columns, data types, stored procedures, and more, showcasing the database schema. Furthermore, our Data Modeling Techniques PPT outlines the step-by-step process of creating a data model using different techniques and tools. Also, the Database Design deck covers the conceptual, logical, and physical data model phases, characteristics, and advantages. Lastly, our Data Model Architecture module presents industry-specific data models for Healthcare, BFSI, Manufacturing, and Retail sectors. You can conveniently download our 100 percent editable and customizable template, compatible with Google Slides, to efficiently design and optimize your data architecture.
People who downloaded this PowerPoint presentation also viewed the following :
Content of this Powerpoint Presentation
Slide 1: This slide introduces Data Schema in DBMS.
Slide 2: This slide depicts the Agenda of the presentation.
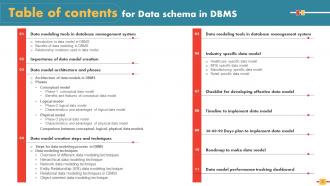
Slide 3: This slide incorporates the Table of contents.
Slide 4: This slide highlights the Title for the Topics to be discussed next.
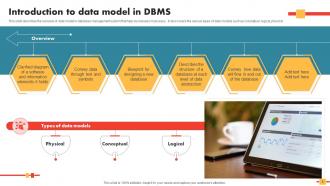
Slide 5: This slide describes the overview of data model in database management system that help businesses many ways.
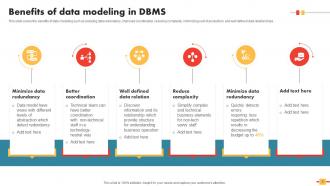
Slide 6: This slide covers the benefits of data modeling such as reducing data redundancy, improved coordination, etc.
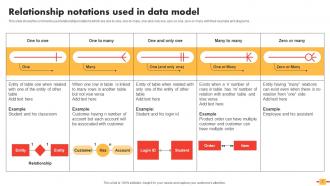
Slide 7: This slide shows the commonly used relationships notations.
Slide 8: This slide includes the Heading for the Components to be covered further.
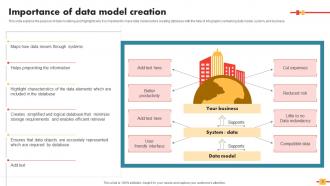
Slide 9: This slide explains the Importance of data model creation.
Slide 10: This slide reveals the Title for the Ideas to be covered in the following template.
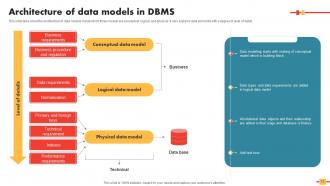
Slide 11: This slide talks about the architecture of data models inside which three models are conceptual, logical, and physical.
Slide 12: This slide displays the Heading for the Ideas to be discussed next.
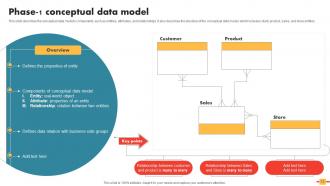
Slide 13: This slide describes the conceptual data model's components, such as entities, attributes, etc.
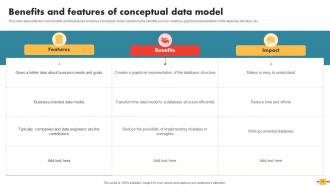
Slide 14: This slide represents the main benefits and the features of using a conceptual model.
Slide 15: This slide mentions the Title for the Topics to be covered further.
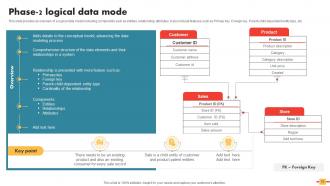
Slide 16: This slide provides an overview of a logical data model.
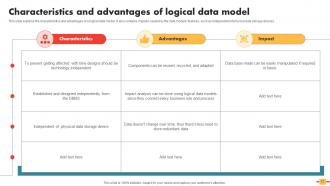
Slide 17: This slide explains the characteristics and advantages of a logical data model.
Slide 18: This slide elucidates the Heading for the Contents to be discussed in the next template.
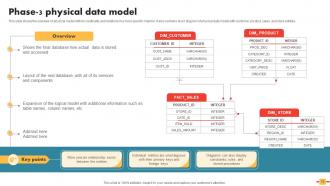
Slide 19: This slide shows the overview of physical model with its cardinality and relations in a more specific manner.
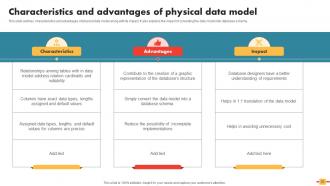
Slide 20: This slide outlines the characteristics and advantages of physical data model along with its impact.
Slide 21: This slide indicates the Title for the Ideas to be covered further.
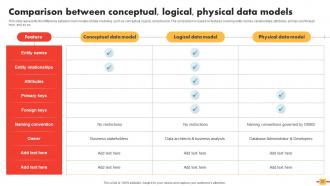
Slide 22: This slide represents the difference between main models of data modeling.
Slide 23: This slide portrays the Heading for the Ideas to be discussed in the following template.
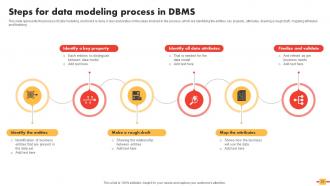
Slide 24: This slide states the process of Data modeling, and how it is done.
Slide 25: This slide shows the Title for the Contents to be covered further.
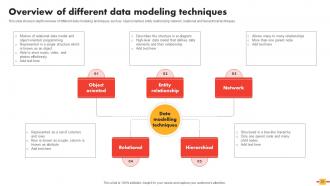
Slide 26: This slide shows in depth overview of different data modeling techniques.
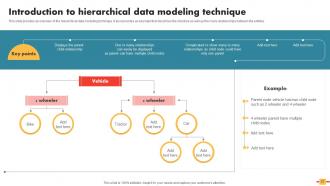
Slide 27: This slide provides an overview of the hierarchical data modeling technique.
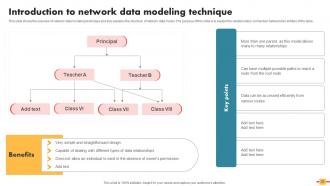
Slide 28: This slide shows the overview of network data modeling technique and also explains the structure of network data model.
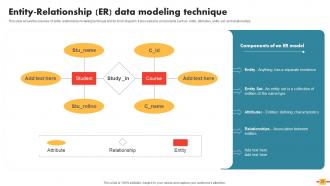
Slide 29: This slide presents the overview of entity relationship modeling technique and its block diagram.
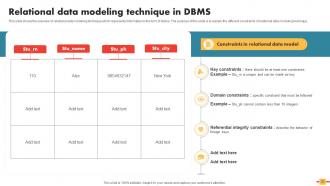
Slide 30: This slide depicts the Relational data modeling technique in DBMS.
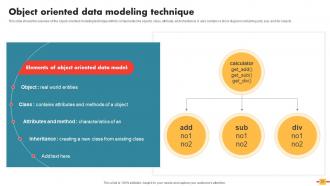
Slide 31: This slide exhibits the overview of the object-oriented modeling technique with its components.
Slide 32: This slide reveals the Heading for the Topics to be discussed next.
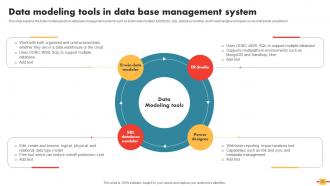
Slide 33: This slide explains the data modeling tools in database management systems.
Slide 34: This slide portrays the Title for the Ideas to be covered further.
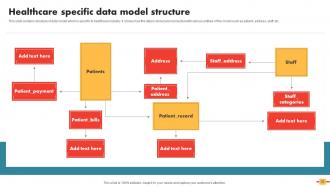
Slide 35: This slide contains structure of data model which is specific to healthcare industry.
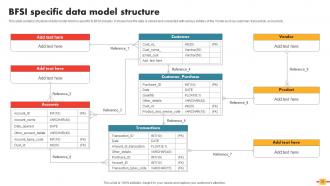
Slide 36: This slide deals with the BFSI specific data model structure.
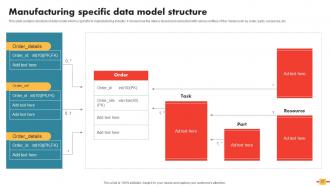
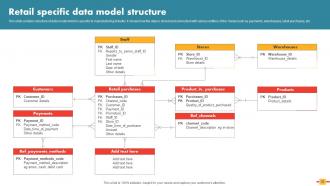
Slide 37: This slide includes the structure of data model which is specific to manufacturing industry.
Slide 38: This slide showcases the structure of data model which is specific to manufacturing industry.
Slide 39: This slide displays the Heading for the Ideas to be discussed in the forth-coming template.
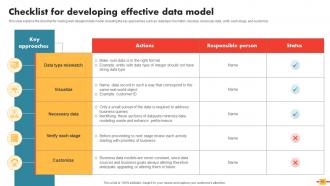
Slide 40: This slide explains the checklist for making well-designed data model.
Slide 41: This slide exhibits the Title for the Topics to be covered further.
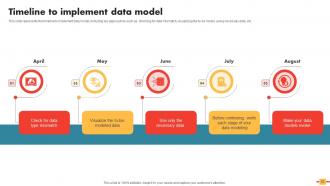
Slide 42: This slide represents the timeline to implement data model.
Slide 43: This slide elucidates the Heading for the Components to be discussed in the following template.
Slide 44: This slide represents the 30-60-90 days plan to implement data model.
Slide 45: This slide reveals the Title for the Ideas to be covered further.
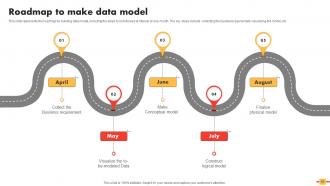
Slide 46: This slide represents the roadmap for building data model.
Slide 47: This slide showcases the Heading for the Ideas to be covered in the following template.
Slide 48: This slide shows the data model performance tracking dashboard.
Slide 49: This is the Icons slide containing all the Icons used in the plan.
Slide 50: This slide depicts some Additional information.
Slide 51: This slide elucidates the mission, vision, and goal of the organization.
Slide 52: This slide showcases information related to the Financial topic.
Slide 53: This is the Venn diagram slide with related imagery.
Slide 54: This is the Idea generation slide for encouraging innovative ideas.
Slide 55: This slide displays the SWOT analysis.
Slide 56: This is Meet our team slide. State your team-related information here.
Slide 57: This is the Puzzle slide with related imagery.
Slide 58: This is the Thank You slide for acknowledgement.
Data Schema In DBMS Powerpoint Presentation Slides with all 63 slides:
Use our Data Schema In DBMS Powerpoint Presentation Slides to effectively help you save your valuable time. They are readymade to fit into any presentation structure.







FAQs for Data Schema In DBMS
So basically, relational databases are super structured - you've got tables with fixed columns and everything has to fit those rules perfectly. Non-relational is way more chill about it. You can throw in documents, key-value stuff, whatever. Relational's awesome when you need complex queries and rock-solid consistency. But honestly? Non-relational scales like crazy and doesn't care if your data structure changes every week (which, let's be real, it probably will). Go relational if you're doing banking or something that can't afford mess-ups. Otherwise, non-relational's probably your friend.
Okay so basically you're splitting up your data into smaller, focused tables instead of shoving everything into one giant mess. Yeah it's more work upfront, but you avoid all that duplicate data and weird inconsistencies. Your queries will need more joins - kinda annoying but worth it for cleaner data. Most people go for 3rd normal form since it hits that sweet spot between removing redundancy and not tanking your performance. Oh and start by figuring out your functional dependencies first, then you can split things up logically from there. Trust me, future you will thank you.
Dude, foreign keys are like your safety net for keeping database relationships intact. You can't reference a customer ID that doesn't actually exist - it'll throw an error before letting you create orphaned records. That cascading delete feature is pretty clutch too; delete a parent record and all the related child records get cleaned up automatically. Honestly, the debugging headaches you'll avoid are worth setting these up from day one. I learned this the hard way on my last project - spent way too much time tracking down broken references that could've been prevented. Short version: they stop your data from turning into a hot mess.
Start with normalization and indexing - that's your biggest bang for buck. Sometimes denormalizing tables that get joined constantly actually helps performance, even though it feels dirty. Index the columns you're always filtering on, but don't go crazy since too many will slow your writes down. Big tables? Partition them by date or whatever makes sense. I learned this one the hard way - pick smaller data types when you can. Saves memory and storage. But honestly, profile your actual queries first instead of guessing what's slow. Way more useful than shooting in the dark.
Ugh, data type mismatches will drive you crazy - seriously, every system handles things differently. Performance gets wonky when queries don't translate cleanly between databases. Edge cases? Yeah, you'll be debugging those forever. Your team's gonna hate learning new syntax, plus there's all the application code updates. Downtime during the switch is always a nightmare too. Oh, and constraint handling varies way more than you'd think between systems. Do yourself a favor though - map out your schema properly from day one. Test with actual data volumes, not some tiny sample that makes everything look easy.
Dude, NoSQL is so much more chill about data structure than regular SQL databases. With SQL you're stuck defining every column and data type before you even start - super rigid. But NoSQL? You can throw different document formats into the same collection and it won't care at all. Need to add a field randomly? Go for it. Some records totally different from others? No problem. You basically decide how to structure things when you're pulling the data out, not putting it in. Really clutch when your project's still figuring itself out or you've got messy, inconsistent data. Though obviously don't go completely nuts with zero planning.
So a star schema is this central fact table with dimension tables around it - picture a star shape, right? The fact table has your actual numbers (sales, quantities, whatever you're measuring). Dimension tables are all the descriptive stuff like customers, products, dates. Honestly it's popular because it just works - queries run fast since the joins are pretty straightforward. Business users love it too since it makes sense to them. Oh, and definitely figure out your main business metrics first, then build everything else around those. That's probably the best way to approach it without overthinking the whole thing.
Definitely start thinking about horizontal scaling right away - partition big tables early because distributed systems hate complex joins. I learned this the hard way on my last project! Cloud-native data types are your friend here. Set up solid indexing and don't forget backup/disaster recovery since your data's living somewhere else now. Auto-scaling is great but watch those costs like a hawk or you'll get a nasty surprise. Keep it simple at first, document what you're doing, and test with realistic loads before launch. Trust me on the testing part.
Oof, schema changes can totally wreck your database if you mess up. I learned this the hard way once - not fun. Blue-green deployments are clutch since you keep two identical environments running. Backward-compatible changes won't break your existing code right away either. Online migration tools help but honestly they're terrifying at first. Test everything in staging, obviously. Plan your rollbacks beforehand and try to do migrations when traffic's low. Start with safe, non-breaking stuff to get comfortable. The scary changes can wait until you're confident.
For schema stuff, I'd go with **dbdiagram.io** first - super clean and your team can actually see what you're talking about. **MySQL Workbench** or **DBeaver** are solid if you want to mess around with existing databases directly. **Lucidchart** works too but honestly feels overkill sometimes. Oh, and **Vertabelo** is decent for web-based work. I spent way too long fighting with some fancy enterprise tool last month when something simple would've done the trick. Just sketch out your current setup first - you'll catch weird relationships and duplicate stuff you totally missed.
Database schema is everything for query speed, honestly. Well-designed indexes and smart table relationships make your queries lightning fast. Miss those indexes though? You're screwed - I've literally watched 30-second queries drop to milliseconds just from adding one index. Normalization matters too, but don't go crazy with it. The trick is thinking about your most common queries upfront when you're designing everything. Way easier than trying to fix performance issues later when your boss is breathing down your neck about slow reports.
So schema-less stuff is pretty flexible - you can throw different document structures at it without planning everything upfront. Development goes way faster and changing data models later doesn't make you want to cry. But here's the thing: you lose those nice consistency guarantees, and query optimization gets weird since the database has no clue what your data looks like. Your app ends up doing all the validation work too. Honestly though, if your requirements change constantly (and whose don't?), it might be worth it. Just don't skip the testing.
Treat your database changes exactly like code - migration scripts in version control that move your schema forward step by step. Each one gets a timestamp or sequence number. Tools like Flyway handle the heavy lifting here, and honestly they're worth it. Run migrations in order during deployment. Try to keep them backward-compatible when you can, though that's not always realistic. Never edit a migration once it's deployed - always create a new file for changes. Oh, and test your rollbacks! I learned that one the hard way. Keep each migration focused on one thing.
Your schema is literally the foundation that determines if your database can handle growth or crumbles under pressure. Get your primary keys and foreign keys right from day one - trust me, fixing a broken schema while traffic is hitting your servers is a nightmare I wouldn't wish on anyone. Proper normalization makes queries faster and saves storage space. Indexing actually works when your structure makes sense. Clean relationships mean you won't hate yourself when adding features later. Oh, and good design makes horizontal scaling way less painful since you can partition data properly across servers.
Start with figuring out what data is actually sensitive - like SSNs, payment stuff, the obvious targets. Then lock down who can access it with proper controls. Encrypt those critical columns and use fake data for your dev environments (seriously, why do developers always think they need real customer info?). Audit logging is huge too - you need to know who touched what and when. Oh, and set up retention policies now before compliance starts breathing down your neck. Map out your sensitive fields first, then build your security around that. Way less painful than trying to bolt everything on later.
-
I discovered this website through a google search, the services matched my needs perfectly and the pricing was very reasonable. I was thrilled with the product and the customer service. I will definitely use their slides again for my presentations and recommend them to other colleagues.
-
“Detailed and great to save your time.”